New articles
On this page
Introduction
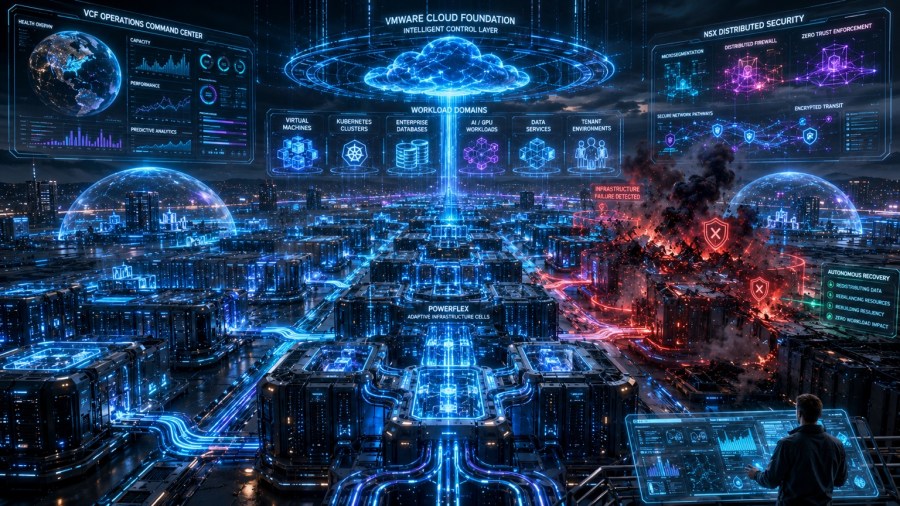
VCF Operations is the visual command center in the image.
The organization can prove who approved the policy, what credentials were used, what commands or APIs ran, what changed, and what the final state became.
The image correctly places security alongside the workloads rather than only at the perimeter.
That does not make an environment zero trust by itself.
Recovery mechanisms can compete. Cluster automation, storage recovery, application clustering, backup tooling, and disaster recovery orchestration may respond to the same event differently.
The triggering condition is based on multiple correlated indicators or a highly reliable platform event.
It is the smallest policy set that accurately expresses the required communication.
The most valuable part of the supplied image is not the futuristic control room or the glowing infrastructure.
The same condition and inputs should lead to a predictable action.
A mature design separates three questions:
What the Image Is Really Showing
A useful observability plane should help the team answer:
Image Zone
Practical Meaning
Important Guardrail
VCF Operations command center
Fleet visibility, health, performance, capacity, diagnostics, and lifecycle context
A dashboard is not an operating model unless signals lead to owned decisions
Intelligent control layer
Policy, lifecycle coordination, governance, placement context, and automation
Central visibility does not eliminate instance, domain, or product ownership
Workload domains
Lifecycle, isolation, capacity, and ownership boundaries for infrastructure services
A workload domain is not automatically required for every application or tenant
NSX distributed security
East-west policy enforcement, segmentation, and workload-aware controls
Zero trust is an architecture discipline, not a single firewall setting
PowerFlex infrastructure cells
An example of a scalable external storage and infrastructure foundation
PowerFlex is not a native VCF control-plane component, and support must be version-validated
Failure and recovery zone
Detection, containment, remediation, recovery, and validation
Availability, local recovery, disaster recovery, and application recovery are different processes
Allow the platform to recommend and prepare a remediation workflow while requiring an operator to approve execution.
A virtual machine that restarted successfully is not proof that its application recovered correctly.
The Closed-Loop Operations Model
Someone remains accountable for the automation after deployment.
Fleet services, VCF instances, management domains, workload domains, clusters, NSX components, storage systems, and recovery services preserve their own responsibilities and failure modes.
What is centrally visible?
It should not make the responsibilities disappear.
Telemetry can be wrong. Missing integrations, stale topology, time drift, collection gaps, and disconnected management packs can produce false conclusions.
Scope and Terminology Guardrails
A management-plane failure is also a governance failure because visibility and change authority may be impaired.
Availability keeps a service running or restarts components after a local failure.
Autonomous Operations
A zero-trust design also requires identity controls, least privilege, device and workload context, strong administrative boundaries, policy review, logging, exception governance, and continuous validation.
This article uses VMware Cloud Foundation 9.1 as the platform baseline, but the mental model applies more broadly to modern VCF 9.x environments.
unrestricted infrastructure changes
an AI model controlling the data center
automatic execution of every recommendation
removal of operator accountability
elimination of maintenance windows
guaranteed zero application impact
This plane absorbs failures first.
Availability, Recovery, and Disaster Recovery
The operating model still matters.
A useful rule is:
The image shows virtual machines, Kubernetes clusters, enterprise databases, AI and GPU workloads, data services, and tenant environments.
Remove duplicate and unactionable alerts before adding automation.
The cluster should identify the failed host, restart affected workloads where policy and capacity permit, preserve network and security behavior, and confirm application recovery.
Security controls can block recovery. Emergency workflows require approved access paths, but broad permanent exceptions create new exposure.
Zero Trust and Micro-Segmentation
Disaster recovery moves or restores services after a larger site, region, or platform failure.
These workloads have different operational characteristics.
The platform can identify the workloads, services, tenants, domains, and dependencies that may be affected.
Intelligent Control
Validation should include the service outcome, not only task completion.
The objective is not the largest rule set.
Assumptions Behind the Model
It is whether critical services returned within their recovery objective.
The target platform is VCF 9.1 or a currently supported VCF 9.x baseline.
VCF Operations and required fleet management services are healthy.
Workload domains and clusters have documented ownership and service purpose.
Identity, DNS, time synchronization, certificates, logging, and administrative access are operational.
Infrastructure and management components have supported backup and recovery procedures.
vSphere availability and placement policies have been designed for the actual workload profile.
NSX policy ownership and emergency-change processes are documented.
Storage topology, protection, capacity thresholds, and failure domains are understood.
Application teams can validate business services after an infrastructure recovery action.
Any PowerFlex integration has been checked against the exact VCF release, hardware, driver, storage, and support matrices in use.
Automation credentials use least privilege and are auditable.
High-impact actions require approval until repeated testing proves they are safe to automate.
Every runbook should state:
The Five Operational Planes
This translation matters because polished architecture imagery can collapse boundaries that remain operationally distinct.
The Observability Plane
Only deterministic, low-risk, reversible actions should move into unattended execution.
The exit criterion is not “we have dashboards.” It is “operators trust the signal enough to act.”
Define a small set of private cloud service-level indicators that operators and service owners understand.
Which service is affected?
Is the condition local, domain-wide, instance-wide, or fleet-wide?
Is the signal a symptom or the root cause?
What changed before the event?
Which workloads and tenants share the dependency?
Is capacity still inside the safe operating envelope?
Which team owns the next action?
What evidence is required before the incident can close?
That visual tells a bigger story than a conventional VMware Cloud Foundation component diagram. It describes an operating model in which the private cloud detects a problem, understands its context, limits the blast radius, selects an approved response, executes that response, and proves that the service recovered.
A management domain can show green CPU and memory while certificate expiration, depot access, identity failure, storage latency, or an unhealthy integration makes the service operationally unsafe.
The Control and Lifecycle Plane
This operating model assumes:
The strongest interpretation of the image is therefore not “VCF heals everything automatically.”
Execution is not success.
Receive new enterprise AI and hybrid platform articles when they are published.
Perimeter controls cannot provide sufficient workload-level containment.
Recovery restores a failed component, service, or workload to an acceptable operating state.
VCF Operations may surface lifecycle workflows and fleet context, but local readiness still depends on SDDC Manager, vCenter, NSX, ESXi, storage, network services, and the health of the relevant management domain or workload domain.
A site event requires a declared recovery decision, verified data state, network transition, identity availability, application sequencing, and business validation.
The Workload and Consumption Plane
Its purpose is not simply to collect more alerts. The purpose is to create operational context.
VMware Cloud Foundation 9.1 can provide a strong foundation for that relationship. VCF Operations can bring fleet health, diagnostics, capacity, and lifecycle context into a more unified operational surface. Workload domains can create meaningful lifecycle and ownership boundaries. NSX can enforce distributed security policy close to workloads. vSphere and supported storage platforms can provide local availability and resilience mechanisms. Protection and recovery services can support broader restoration and disaster-recovery workflows.
The validation question is not only whether the virtual machines powered on.
Security automation should therefore include:
These actions reduce response time without granting broad infrastructure authority.
An unowned workflow becomes technical debt with production credentials.
lifecycle independence
security isolation
administrative separation
hardware specialization
storage architecture
availability requirements
regulatory evidence
tenant governance
upgrade scheduling
blast-radius containment
Automate data collection, prechecks, evidence capture, health validation, ticket updates, and other low-risk tasks first.
The Distributed Security Plane
Continue with the path that best matches the architecture or operating challenge in front of you.
Where those requirements do not differ, additional domains may create more management overhead than operational value.
A recovery workflow that has never been tested is an assumption, not a capability.
It is the decision and policy gate.
Healthy infrastructure can host an unhealthy application. Infrastructure validation must be connected to service validation.
The workflow is not launched by a noisy threshold with a history of false positives.
policy ownership
approved object and naming standards
change evidence
rule-hit and flow analysis
exception expiration
rollback procedures
application-owner validation
break-glass access
drift reporting
A domain boundary is justified when it materially improves one or more of the following:
Compute, network, and storage form the physical and software-defined substrate beneath every VCF service.
The Resource and Resilience Plane
A private cloud becomes operationally intelligent when it can turn infrastructure signals into controlled, verifiable outcomes.
The incident record should capture what happened, what action ran, what changed, whether rollback was required, and whether the automation remains approved.
Autonomy should be earned in stages.
A host failure may trigger workload restart through vSphere HA. Resource pressure may lead to placement or balancing activity. A storage platform may rebuild protection after a component failure. NSX can preserve network and security constructs as workloads move. Recovery tooling can coordinate restoration or failover for larger incidents.
Not every recovery action deserves the same autonomy.
That is how VCF becomes an autonomous operations fabric without becoming an uncontrolled one.
host
rack
cluster
storage fault set
network fabric
management domain
workload domain
VCF instance
site
region
shared external dependency
A host restart, storage rebuild, network convergence event, management-plane restoration, and site failover have different dependencies, time scales, risks, and validation requirements.
Autonomous Recovery Is a Maturity Model
The purpose is to establish sensible lifecycle, isolation, capacity, ownership, and failure boundaries.
A general-purpose virtual machine cluster may prioritize consolidation and mobility. A database platform may prioritize latency consistency and data protection. An AI cluster may require GPU-aware placement, large memory capacity, high-throughput storage, and more restrictive maintenance windows. A tenant platform may require stronger identity, quota, network, and evidence boundaries.
Containment and rollback must preserve evidence.
Observe
Measure recommendation accuracy, execution success, rollback frequency, and service impact.
That is the right ambition for VCF operations.
Correlate and Diagnose
The flow should look like this:
The platform must verify infrastructure health, workload readiness, application service behavior, security state, data integrity, and the original service objective.
Recommend
It is this:
Storage telemetry without topology context can lead to the wrong action.
Execute with Approval
Autonomy appears when the organization connects them through explicit policy, constrained authority, tested workflows, rollback, service validation, and visible ownership.
Start with service inventory, ownership, topology, critical dependencies, capacity thresholds, and alert quality.
Execute Within Policy
When the failure domain is unclear, automation may move workloads directly into another part of the same failing system.
The image places PowerFlex beneath the workload domains as a collection of adaptive infrastructure cells.
Validate and Learn
Without that gate, an environment has event-driven scripts. It does not have governed autonomous operations.
VCF Operations may show the condition of the environment, but vCenter, ESXi, NSX, the storage platform, protection tooling, automation services, and application owners still perform different roles. A healthy operating model connects those roles without pretending they have become one product.
Choosing What to Automate
Limit execution by environment, workload tier, maintenance policy, time window, and blast radius.
Condition
Likely Response
Recommended Initial Posture
A single VM process has failed
Application or guest recovery workflow
Approval or application-owned automation
An ESXi host has failed
vSphere HA and cluster recovery behavior
Platform-native automation with monitoring
Cluster imbalance exceeds policy
Placement or balancing action
Policy-based execution after capacity validation
Storage component is degraded
Storage rebuild, isolation, or vendor runbook
Storage-platform automation plus operator oversight
Distributed firewall drift is detected
Restore policy, quarantine, or open incident
Detect automatically, approve high-impact changes
Certificate is nearing expiration
Renewal workflow with dependency checks
Automate after nonproduction validation
Management service is unavailable
Restore service or management appliance
Runbook-driven recovery with escalation
Site failure is declared
Orchestrated disaster recovery plan
Explicit authority and business approval
Application validation fails after recovery
Stop progression or initiate rollback
Automatic stop, human-led diagnosis
This is especially important for autonomous operations.
Modern private cloud traffic is heavily east-west. Application tiers, APIs, databases, container services, shared infrastructure, and management systems communicate inside the data center.
Where PowerFlex Fits
Automate the repeatable mechanics, not the unresolved decision.
These mechanisms do not share the same scope.
Most private cloud diagrams show a steady-state platform.
Document the expected response for common host, cluster, storage, network, certificate, lifecycle, and management-service conditions.
The image can be translated into five planes that should be designed and operated deliberately.
the exact VCF and ESXi release
supported PowerFlex software and SDC versions
driver and firmware compatibility
storage protocol and datastore type
principal versus supplemental storage rules
management-domain storage requirements
workload-domain deployment workflow
vSphere HA heartbeat behavior
multipathing and failure handling
lifecycle ownership
monitoring and alert integration
backup and recovery dependencies
vendor support boundaries
The autonomous operations model introduces its own risks.
The storage platform should identify the affected component or path, maintain data availability where protection allows, begin the appropriate recovery process, and expose the degraded state to operations.
The architecture should be tested against realistic failure scenarios rather than only component availability claims.
Decision Criteria for Bounded Autonomy
Automatically disabling a firewall rule is rarely an acceptable first response.
The Signal Is Trustworthy
Organizations should not jump directly from alerting to autonomous execution.
The workflow should use version-controlled logic, constrained credentials, execution logging, and explicit timeout behavior.
The Action Is Deterministic
Centralization should improve coordination. It should not blur responsibility.
NSX distributed firewall policy can place enforcement closer to workloads and support micro-segmentation strategies. This allows policy to follow workload identity and application context more closely than a design that relies entirely on physical network boundaries.
The Blast Radius Is Limited
“Run the script again in reverse” is not a rollback design.
The system knows what healthy means after the action.
The Action Is Reversible
Workloads may continue running while operational control is degraded.
The system proposes an action, explains the evidence, identifies the blast radius, and lists validation and rollback steps.
Success Can Be Measured
That is a reasonable visual metaphor for scalable software-defined storage, but the architecture boundary must remain clear.
Management services are dependencies. Centralized operations improve control, but their own availability, backup, identity, and recovery designs become more important.
The Action Is Auditable
Include failed hosts, path loss, capacity pressure, expired credentials, service outages, policy errors, management-plane restoration, and application validation.
Ownership Is Explicit
Who is accountable for the result?
A workflow that depends on undocumented operator intuition is not ready for unattended execution.
Operational Ownership Model
The important qualification is that autonomy must be bounded. A platform should not make high-impact infrastructure changes merely because an alert fired or an analytics engine produced a confident recommendation. The response must be constrained by policy, service criticality, failure-domain knowledge, application dependencies, and a documented authority model.
Capability
Accountable Owner
Required Evidence
Fleet health and observability
VCF operations owner
Service dashboards, alert quality, diagnostic backlog
Instance and management-domain health
VCF instance owner
Prechecks, backups, component health, recovery runbooks
Workload-domain readiness
Domain owner
Capacity, lifecycle state, maintenance readiness
Compute availability
Virtualization owner
HA behavior, admission control, restart validation
NSX policy and segmentation
Network and security owners
Approved policy, realized state, exception review
Storage resilience
Storage owner
Protection state, path health, capacity, rebuild status
Recovery orchestration
Resilience or DR owner
Recovery plan, test evidence, rollback criteria
Application validation
Application or service owner
Functional tests, data integrity, business acceptance
Automation policy
Platform governance owner
Approval scope, credential model, audit history
Incident command
Designated incident owner
Timeline, decision record, communications, closure evidence
It does not mean:
Automation can amplify mistakes. A manual error may affect one object. A fast automated workflow may affect hundreds.
Failure Scenarios the Model Must Survive
Zero workload impact is an objective, not a default outcome. Some failures will interrupt services. Good architecture reduces impact, detects it quickly, and recovers predictably.
Host Failure
VCF Operations can unify context across these responsibilities.
The image represents a mature destination. Most organizations should approach it incrementally.
The objective is to reduce duplicate alerts and avoid treating every symptom as an independent incident.
Storage Degradation
The platform collects reliable health, capacity, event, configuration, and dependency signals.
Where is the change executed?
Network or Security Policy Failure
Autonomous operations should distribute responsibility rather than concentrate it invisibly inside the tooling.
It includes fleet-level services as well as the instance and domain management components that execute local infrastructure changes.
The response should prioritize restoration of management access, identity, DNS, certificates, database health, storage connectivity, and dependent services.
Management-Plane Failure
An operator or service owner reviews the evidence and authorizes a predefined workflow.
The recovery controller cannot safely respond to a storage event unless it understands whether the condition is a transient path issue, host-side driver problem, capacity problem, rebuild event, protection loss, or array-level failure.
Run controlled resilience exercises.
Site Failure
Keep exploring
One part of the infrastructure is burning. Security boundaries are visible around the affected zone. The operations command center is still collecting signals. Workload domains remain represented as separate service areas. A recovery panel shows data redistribution, resource rebalancing, resilience rebuilding, and an objective of zero workload impact.
Dell has published implementation guidance for using PowerFlex as principal storage for VCF 9.0 management and workload domains, including a VMFS on Fibre Channel design through the PowerFlex SDC. That guidance is useful, but it should not be treated as automatic proof of support for every VCF 9.1 configuration.
A Practical Implementation Path
It is the relationship between visibility, security, failure containment, and recovery.
Build a Trusted Observability Baseline
The purpose of workload domains is not to create a separate domain for every workload label.
The image is not a literal deployment topology. It is a mental model that combines several technical and operational layers into one visual environment.
Those capabilities do not automatically create an autonomous private cloud.
Standardize Policy and Recovery Runbooks
Broad fleet-wide changes should require stronger authority than a local low-risk correction.
Several terms require explicit boundaries.
trigger
owner
prerequisites
decision criteria
action
validation
rollback
escalation
evidence retained
Convert Manual Mechanics into Approved Workflows
The control layer should be understood as coordinated operations and policy, not as one centralized component that directly performs every infrastructure action.
Before using PowerFlex in a VCF 9.1 design, verify:
The platform connects infrastructure symptoms with topology, recent changes, service ownership, and dependency context.
Autonomous operations means the platform can execute approved actions inside a defined scope without waiting for a human to repeat an already-governed decision.
Enable Narrow Closed Loops
Compute is healthy. Storage is available. Networks are connected. Security policies are enforced. Management services are online. Every arrow moves in the expected direction.
The organization should already have evidence that the action behaves safely across normal failure scenarios.
Test Failure and Recovery Regularly
This is why service-oriented dashboards are stronger than product-oriented dashboard sprawl. Operators should begin with the health of a private cloud service, then move downward into component evidence.
The control plane coordinates configuration, lifecycle, inventory, and policy.
PowerFlex is an infrastructure platform integrated with VCF through supported storage and host connectivity designs. It does not replace VCF Operations, SDDC Manager, vCenter, NSX, or workload-domain lifecycle controls.
Operational Risks and Caveats
Application recovery confirms that the business service works after infrastructure has been restored.
The resilience plane should therefore be designed around explicit failure domains:
Version support is not implied by architectural similarity. Storage, network, protection, driver, firmware, and integration support must be checked against the exact deployed baseline.
Move only proven, deterministic, reversible actions into unattended operation.
The environment should determine whether the issue is transport, routing, name resolution, load balancing, firewall realization, group membership, or application policy.